For folks watching the AI litigation horizon for signs and portents of the future of fair use (it’s not just me, right?), this past Friday was a big day: the deadline for filing amicus briefs in In Re Open AI, Inc, Copyright Infringement Litigation. OpenAI holds the distinction of being a defendant in a plurality of the 150+ AI lawsuits currently winding their way through the federal courts, several of which have been consolidated into a single proceeding before Judge Sidney H. Stein in the Southern District of New York. That consolidation of claims from book authors and news publishers attracted the efforts of a wide variety of ‘friends of the court,’ who shared their perspectives in an avalanche of over 50 amicus briefs.
A good amicus brief presents the court with technical, legal, or policy information that the parties have not already addressed. Many of the briefs filed on Friday fit that description, though some briefs added more than others.
Naturally there are already a couple of very nice vibe-coded dashboards that allow you to browse these briefs and see various summaries of their contents. Re:Create highlighted member and ally briefs in a memo, Ed Lee has a simple one that lets you find and view briefs much more easily than the unwieldy docket view on Courtlistener, and the Chamber of Progress has a more elaborate dashboard that lets you view the briefs by issue and argument across a number of dimensions. Below is my artisanal take, grouping the briefs into a handful of categories based on my own sense of their essential character:
Fair Use Stalwarts
These amici are dedicated friends of fair use, most with decades of experience intervening in cases like this one, and they showed up to defend core principles in fair use law. Most of these briefs are in support of OpenAI’s motion for summary judgment, although a few styled their briefs as “in support of neither party.” They focused on aspects of the plaintiffs’ argument that would upset longstanding fair use principles, especially the so-called “market dilution” theory and the notion that you can show market harm simply by demanding payment for the use at issue. These groups also affirmed that AI training is strongly “transformative,” and therefore highly favored by fair use. These parties are anxious to ensure that fair use continues to play its traditional role of checking copyright’s market monopoly to enable innovation.
Not surprisingly, Re:Create member orgs are generally in this category, including Public Knowledge, the Electronic Frontier Foundation, CCIA, Engine, and the Consumer Technology Association (with the Association of Research Libraries, the American Library Association, the Business Software Association, and the Nat’l Fed’n of the Blind). The Authors Alliance’s excellent brief is also in this category, as is the brief for Copia Institute and Floor64.
Protectionist Stalwarts
The yin to Re:Create’s yang, the Protectionist Stalwarts are orgs that have spent decades fighting (and losing, mostly) a war to stop fair use-powered innovation and creativity. From the VCR to the search engine, from Google Books to the Android operating system, these groups show up in court to argue that fair use is a mere defense, a blip, a tiny exception to copyright’s default rule of total rightsholder control. The Copyright Alliance, the RIAA, the NewsMedia Alliance, and the AAP are all in this category. Their goal is not just for their members to make a buck from AI, but to shrink fair use generally, at the expense of the public. Accordingly, their arguments take broad aim at important concepts like transformative use, which they’d like to relegate to a minor footnote. They attempt to distinguish and minimize fair use precedents and to construe the Supreme Court’s most recent fair use decision in Warhol as a pendulum swing away from the transformative use revolution inaugurated in Campbell v. Acuff-Rose. Hopefully the court will resist their invitation to turn the fair use tide after decades of steady progress favoring the public.
AI’s Public Beneficiaries
The fair use calculus has always included the public benefits of a use, a sub-factor highlighted in the Supreme Court’s opinion in Oracle v. Google. Since neither party can fully represent “the public,” amicus briefing on behalf of these beneficiaries can help courts better evaluate this sub-factor. The CTA-led brief is a powerful example of this strategy, assembling information about fair use-trained AI’s benefits for doctors and patients, people with disabilities, educators and librarians, and many other groups.
Two other briefs focus on the benefits of AI fair use specifically for creative people. The Chamber of Progress and the Abundance Institute joined a brief with the multi-Grammy winning drummer Trevor Lawrence, Jr. (collaborator with Dr. Dre, Kendrick Lamar, Bruno Mars, Alicia Keys, and others), to argue that AI is just the latest technology tool to empower musicians’ creativity, not replace it. Similarly, indie creators Sarah Rose Siskind and Michael Wall file a brief explaining how AI can help new creators succeed without the backing of major corporate studios, in part by simplifying administrative tasks and freeing more time for creative work. Wall’s and Siskind’s personal experiences refute core factual claims in the plaintiffs’ and their amici’s briefs about the net-negative impact of AI on human creativity.
Another beneficiary brief comes from Greg Leppert, a data scientist who works with libraries and is currently the head of the Institutional Data Initiative at Harvard Law School. Leppert argues that general purpose AI tools offer libraries unprecedented opportunities to make the information in their collections accessible and usable for the public.
The brief for Midjourney and Runway, AI Progress, and other AI companies and investors (described below in their own category) also include strong arguments about the public benefits of AI.
Members (and former Members) of Congress
Two briefs were filed by groups of current and former legislators. The current legislators’ brief was filed on behalf of Democratic House Judiciary Committee members Jamie Raskin, Gerrold Nadler, and Hank Johnson. Their brief doesn’t explicitly take sides between the Plaintiffs and the Defendants, focusing its fire instead on the Justice Department’s “Statement of Interest” in the case. The brief combines partisan jabs (the DOJ is accused of misinterpreting the law and acting without input from the Copyright Office) with fan service to the big content companies that leaders on the Judiciary Committee have long treated as primary stakeholders. While the brief doesn’t expressly side with the plaintiffs, the bulk of its arguments are attacks on the DOJ’s support for broad fair use. That said, the brief mostly faults the DOJ for the sweeping nature of its intervention, saying that fair use for AI training should be more case-by-case rather than categorical. Thus, the members’ brief is not necessarily inconsistent with a decision in favor of OpenAI in this case.
The retired legislators’ brief was filed on behalf of former Senators Rick Boucher and Rick Santorum, and it focuses on how permitting AI training as a fair use would be consistent with the innovation-promoting goals of the fair use doctrine in copyright law. Senator Boucher was a consistent champion for fair use and the open internet in his time as a legislator, and the brief reflects his experience on the front lines of policy as the American internet economy grew into global leadership thanks in large part to fair use. As such, it offers a clear counterpoint to the other legislators’ brief.
Lawprofs: Fair Use Experts
Law profs piled into this docket in droves – so many that we can break them into sub-categories. The first is for the hardcore fair use scholars whose work has long focused on fair use and related issues. Matthew Sag is in this category, as are Rebecca Tushnet and Ed Lee, and Pam Samuelson and Chris Sprigman. Like the Stalwarts, the Experts are focused on helping the court understand the deep logic of fair use and the importance of preserving fair use rights against encroachment from plaintiffs. Lee and Tushnet add a Constitutional dimension, explaining how plaintiffs’ market dilution arguments run afoul of the First Amendment. I expect these briefs to have an impact because they offer the court deeper insights into the current state of the legal doctrines squarely at issue in the case.
Lawprofs: Protectionists and Social Justice Folks
Where the Fair Use Experts are generally aligned with the Second Circuit’s (and other courts’) current interpretations of fair use and write to help Judge Stein understand and stay within that mainstream view, other scholarly amici have a more activist agenda. The Protectionists are scholars (Sandra Aistars, Justin Hughes, Séan O’Connor, and several others) who have long disagreed with the courts’ generally expansive view of the fair use doctrine. Accordingly, they argue that fair use should be narrowly interpreted in this case to exclude AI training, which would turn the doctrine in a new direction relative to the last 30 or so years of judicial decisions.
The Institute for IP and Social Justice promotes a view of copyright that centers “socially equitable access, inclusion, and empowerment.” This view sometimes aligns with the protectionist view (when the copyright holders at issue are from marginalized communities, for example), but in other cases joins the mainstream view favoring fair use (when the use increases access to information across socio-economic barriers, for example). Fittingly, then, the brief supports neither party here, and devotes most of its pages to explaining the IP social justice perspective and arguing that this perspective should be kept in mind by Judge Stein and other courts as they evaluate AI cases.
AI Labs and Investors
The outcome in this case obviously threatens to reverberate throughout the ecosystem of artificial intelligence developers and investors, so several briefs in the case represent the interests of other denizens of that ecosystem. AI Progress is a coalition of most of the big AI companies you’ve heard of, including OpenAI, Anthropic, and Google, and their brief recapitulates the core fair use arguments in the OpenAI and Microsoft briefs. Investment firm Khosla Ventures filed a brief arguing that a decision for plaintiffs will slow investment in the AI sector, risking American leadership in the global AI race. Midjourney and Runway are AI companies working in the visual realm, using diffusion technology trained on copyrighted material in much the same way that large language models are trained on text. Their brief focuses more on the benefits of AI technology, as evidence both of its value and of its transformativeness. Fittingly, the Midjourney-Runway brief is the only one with images.
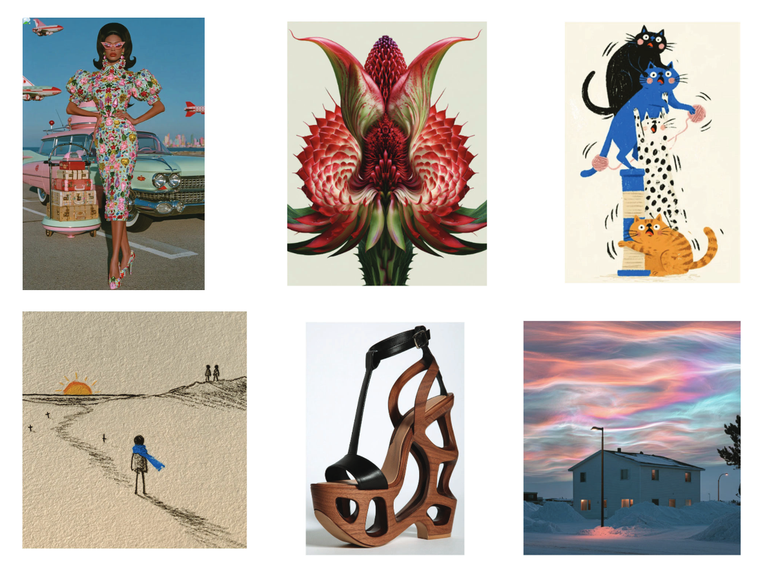
News Exceptionalists
Two briefs take the position that news reporting is so important to a democratic republic that the economic health of the current leading news publishers should override ordinary copyright doctrine. A group of “First Amendment Scholars,” including Jack Balkin, offers the court a lesson in the importance of a free press, repeats the News Plaintiffs factual claims about alleged harm to news publishers from AI training (citing to the Plaintiffs’ brief as its primary source of evidence), and concludes that the court should rule for the news plaintiffs because journalism is important to democracy, all without any reference to copyright (literally, the word “copyright” only appears in the brief twice, both times as part of the name of the case – “In re OpenAI copyright infringement litigation”).
The brief filed on behalf of PEN America, Reporters Without Borders, and Protect Democracy Project doesn’t eschew copyright entirely, but makes a historical argument that copyright ought always to be subservient to press freedom. The brief explains, for example, how news reporting was not copyrightable under the first Copyright Act of 1790 because most news publishers did not own what they printed and the Founders wanted to encourage printers to facilitate the widest possible distribution of news. Later, news reporting gained copyright protection as Congress recognized the utility of rewarding publishers’ investments in reporting. Rather than conclude that the link between copyright and the encouragement of news reporting is historically contingent and may change with technology and business models for news, the brief instead urges the court to unilaterally expand copyright for news publishers alone to protect their current business model, even if fair use might protect similar behavior involving other forms of copyrighted works.
RAG Differentiators
Several briefs single out retrieval augmented generation (RAG) for special treatment, or carve it out of their otherwise fair-use-friendly argument. Wikipedia’s brief reflects its complex interests in this space. On one hand, they support fair use for training as consistent with their general orientation in favor of fair use and innovation; but like many website publishers, they are anxious that information sourced from Wikipedia but accessed through AI interfaces won’t earn the site goodwill or devoted users in the way that search referral traffic did. Accordingly, they argue that training should generally be fair use but “RAG” (the process by which AI answers are grounded in contemporaneous web searches) should not. I’m not sure this is a position that will win much support in the Second Circuit, home of the Google Books case and “snippet view.” Public Knowledge, Joshua Gans, and Matthew Sag all say training is generally fair but RAG uses need separate, case-by-case evaluation, which may go different ways in different cases. Former Googler Jim Albrecht takes no position on training, but focuses his brief on why RAG is not fair use, at least when applied to news.
Techies: An Army of Computer Scientists vs. Some Skeptical Brits
A brief filed on behalf of a laundry list of computer scientists (most of the 106-page brief consists of CVs of the signatory scholars) offers the court a detailed technical refutation of the plaintiffs’ core factual claims about how AI works. Because the fair use analysis depends on “whether a trained model ‘stores and retrieves copies’ of copyrighted works and whether models ‘reproduce protected expression to the public,’” the computer scientists’ brief argues that their technical argument that neither of those claims is true should be important to the court’s fair use analysis. The technologists do a good job tying their technical points to the fair use factors. For example, they explain that because an LLM is by its nature a general purpose tool and not a copy of its training data, training an LLM is a transformative use under the first factor. They walk through all four factors, making similar connections between their technical analysis and the fair use analysis.
A contrasting brief, filed by the Minderoo Centre at Cambridge University in the U.K. (an ‘independent team of academic researchers’ who believe ‘uncontrolled accumulation of power by technology companies poses major threats to democracy and the natural environment’), urges the court to reject all motions for summary judgment because they say important factual questions remain about whether and to what extent AI training leads to memorization. Between the parties’ briefs and the computer scientists’ brief, I’m not sure the court will agree with Minderoo on this.
Dueling economists plus alleged antitrust experts who think stronger monopolies are good for competition
A brief filed on behalf of economist Joseph Stiglitz recapitulates the economic arguments he and a co-author advanced in a 2025 research paper. Based on that paper’s conclusion that AI products threaten to displace human-authored works in the marketplace, the brief argues that the first and fourth fair use factors should tilt against fair use. Among the non-copyright scholars’ briefs, this one does a better job connecting the filer’s agenda to copyright doctrine.
A contrasting brief filed on behalf of economist Joshua Gans implicitly challenges Stiglitz’s economic substitution and harm arguments. Gans urges the court to distinguish between problematic substitution and beneficial learning and commentary, and to consider the adverse effect that forced licensing would have on subsequent beneficial uses. Like Stiglitz, Gans’s brief does a good job connecting his economic arguments directly to copyright doctrine.
A third brief focused on competition comes from the ‘hipster antitrust’ crowd at the Open Markets Institute. Their brief joins the chorus of plaintiffs’ side briefs arguing that ChatGPT is a competing substitute for access to the works it trains on. Unfortunately, other than repeating the plaintiffs’ arguments in its voice, the OMI brief adds little to help the court come to a better decision.
Wannabe licensors (and licensees)
Many of the amicus briefs filed on the Plaintiffs’ side represent groups who want a piece of the AI investment boom in the form of licensing revenue. These groups make two slightly contradictory arguments: AI tools threaten to replace us, and we would be happy to authorize them to do so for an appropriate fee. Groups in this category include the Association of American Publishers, William Morris Endeavor, the AI Coalition for Data Integrity (joined by several creator guilds and unions), Digital Content Next, and Creative Artists Agency et al. For obvious reasons, these groups are anxious to have the court embrace the circular argument that lost licensing revenue counts as market harm, forcing AI labs into their arms as customers.
That’s not the only fallacy in these briefs. Others include “If it’s possible to pay me or my clients a fee, then it is possible to identify, contact, and negotiate a fee with all of the trillions of owners of works in a typical AI training dataset,” and “If I can get someone to agree in a contract to limit how they use AI on my clients’ work, then copyright should force everyone in the world to follow the same limitation.” The primary contribution of these briefs is likely to be information about the feasibility of licensing at least some of the works in a typical training dataset. To win the court over, they’ll have to get past arguments like this from Midjourney:
Even if one could ascertain the author, find their contact information, confirm the work remains under copyright and the counterparty has authority to license it, initiate negotiations, and successfully come to terms (e.g. price, scope of use, and appropriate representations and warranties) in the span of a single minute—which is, of course, absurd—licensing a million works would take a million minutes, or roughly 1.9 years, and licensing a billion would take nearly two thousand years.
Creative Worker Unions and Guilds
Several amicus briefs were filed by unions, guilds, and other groups representing creative workers, all generally in support of the Plaintiffs and against fair use. Examples include briefs for SAG-AFTRA, for groups of Authors, Photographers, Playwrights, and Literary Translators, and for LION and the Society of Professional Journalists et al. These briefs generally make a couple of core arguments. One is a trickle-down argument: although most people who do creative work for hire (actors, staff writers, editors, and others) never own copyrights, their livelihood depends on their bosses’ exploitation of copyrights, so AI licensing revenue that flows to the bosses could eventually trickle down and benefit them. Another is the same substitution/dilution argument made by the parties and most amici: that new, non-infringing works created with the aid of AI should count as harmful substitutes in the fair use analysis. Like William Morris, the Guilds argue that because they can use contracts to set limits on how their bosses use AI, copyright law should allow them (or their bosses) to control how everyone else uses AI. These briefs’ main contributions are additional expressions of anxiety about AI-powered replacement and competition. Their legal arguments add little to what’s already in the News and Books plaintiffs’ briefs.
National Security
The Foundation for American Innovation argues that leading the global race to develop the most powerful AI tools is a U.S. national security priority, and should be weighed in favor of fair use. They give examples of how government agencies rely on private industry AI tools, which themselves rely on fair use to train. The Steve Bannon-allied Center for American Rights argues the opposite – that ‘protecting IP’ is the real national security priority (tell that to the folks who lose power to a hacking attack…), so broad fair use is inconsistent with national security interests.
Random celebrities
Mixed in with the scholars, trade associations, and unions are a handful of what can only be called random celebrities. Ashley Judd, Ken Burns, Cate Blanchett, and…Nicholas Hexum (the singer guy from 90s rap-rockers 311) all show up in the docket to endorse the news or books plaintiffs’ arguments. One suspects that the main goal of these famous names is to get some press attention for their position, and it worked.
Silicon Valley celebrities
Kevin Kelly and Michael Moritz are what you might call Silicon Valley celebrities – tech thought leaders and investors with enough profile to file their own briefs. Kelly is a co-founder of Wired and a Bay Area guru figure. Moritz is a billionaire investor and former journalist. Each of these folks is interesting. Their briefs…not so much. Kelly thinks AI is an exciting innovation, so it should be protected by fair use. Moritz wants to contain his two identities by praising AI but expressing hope that licensing solutions could be a win-win.
Head scratchers
A couple of briefs seem to exist mainly as a vehicle for one person’s slightly off-center thoughts on AI and copyright. One might best be described as the David Atkinson fan club. Co-signed by a motley crew of non-profits and individuals generally critical of AI technology, the brief essentially recapitulates Atkinson’s paper “Unfair Learning: GenAI Exceptionalism and Copyright Law,” which rebuts a popular lay argument that AI training is like human learning and so it shouldn’t have to be licensed. Just as these groups don’t really touch the mainstream conversation about AI policy, their intervention here doesn’t really make contact with copyright law or the hardcore copyright issues in the case. Jim Ko is…an Arizona patent lawyer. Ko has branded himself as an AI lawyer and has big ideas about copyright that the court is not likely to find more persuasive than its own precedent.
Judge Stein and his clerks have a lot to think about. As one smart friend observed, end-of-summer 2027 might be a milestone to watch for in terms of getting an opinion on these motions, as that’s when Stein’s law clerks would turn over. We might get word sooner than that, but probably not later, as he’d likely prefer to have the current clerks’ help in finalizing his opinion.